Seyed Masoud Hosseini · Overview · Study log · Ideas · Transcript · RSS feed
Matrix Methods for Data Analysis & ML · Lecture 7 of 36 · 45:27
Lecture 5: Positive Definite and Semidefinite Matrices
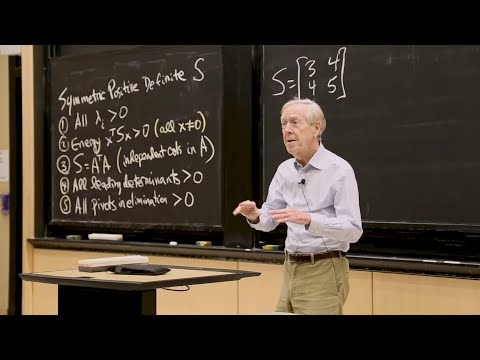
Study guide
What this lecture covers
This lecture closes Strang's five-lecture review of linear algebra highlights by focusing on positive definite matrices, the best of the symmetric matrices. He lays out five equivalent tests for positive definiteness (positive eigenvalues, positive energy, positive leading determinants, positive pivots, and a factorization test) and works a 2x2 example through most of them, showing how to adjust a matrix to make it positive definite.
The middle of the lecture connects positive definiteness to the "energy" function x^T S x, its bowl-shaped graph, and why this shape is exactly the loss surface that gradient descent tries to minimize in machine learning. The lecture ends with positive semidefinite matrices as the borderline case. After watching you should be able to test whether a small symmetric matrix is positive definite, explain what the energy function represents geometrically, and describe how gradient descent finds a minimum.
Key ideas
- Five equivalent tests for positive definiteness: positive eigenvalues, positive energy (
x^T S x > 0for all nonzerox), positive leading determinants, positive pivots from elimination, and a factorization such asA^T A; passing any one test guarantees a matrix passes them all. - Energy function:
x^T S xexpands into a quadratic like3x^2 + 6y^2 + 8xy, and for a positive definite matrix this function is always positive except at the origin, producing a bowl-shaped graph. - Positive definiteness as a loss function shape: the bowl-shaped energy graph is the model for a convex loss function in machine learning, with the true loss adding linear or nonlinear terms and often losing convexity in deep learning.
- Gradient descent: from a starting point, compute the gradient (vector of first derivatives), step downhill in that direction, stop, and repeat; deep learning relies on first derivatives only, since second derivatives are impractical with hundreds of thousands of variables.
- Eigenvalue spread and slow convergence: when a bowl is long and thin (eigenvalues far apart in size), gradient descent zig-zags slowly across the narrow valley instead of heading straight to the minimum; a circular bowl (equal eigenvalues) converges directly.
- Sums, inverses, and similarity preserve positive definiteness: if
SandTare positive definite, so isS + T(energies add) andS^-1(eigenvalues invert but stay positive);Q^T S Qfor orthogonalQis positive definite because it is similar toS, or because its energy reduces to the energy ofSat a transformed vector. - Positive semidefinite matrices: the borderline case where eigenvalues are greater than or equal to zero; a rank-one matrix like the all-ones matrix has one positive eigenvalue and the rest zero, making it positive semidefinite but not positive definite.
Walkthrough
Five tests and an indefinite example (3:02)
Strang introduces the five equivalent tests for positive definiteness and applies them to a symmetric 2x2 matrix with a negative determinant, showing it is indefinite (one positive and one negative eigenvalue) even though all its entries are positive. He then adjusts the matrix by increasing a diagonal entry and shows the leading (upper-left) determinants and the elimination pivots become positive, illustrating how the tests connect.
The energy function and its bowl (9:08)
Strang expands x^T S x for the adjusted matrix into 3x^2 + 6y^2 + 8xy and graphs it as a function of two variables, showing it rises like a bowl above the plane, touching zero only at the origin. He connects this directly to machine learning: a loss function measuring error between training data and predictions has this same bowl shape in the simplest case, though real loss functions add linear terms and often nonlinear ones.
Gradient descent and the effect of eigenvalue spread (20:24)
From a starting point on the bowl, Strang describes gradient descent: compute the gradient (all first derivatives), step downhill along it until the path starts turning back up, then repeat from the new point. He explains that computing only first derivatives, not second derivatives, is what makes this feasible for hundreds of thousands of variables. He then shows that when a bowl is long and thin, meaning its eigenvalues are very different in size, gradient descent zig-zags across the narrow valley and converges slowly, while a circular bowl with equal eigenvalues converges directly to the minimum.
Combining positive definite matrices (29:39)
Strang works through several quick exercises: the sum of two positive definite matrices is positive definite, shown by adding their energies; the inverse of a positive definite matrix is positive definite, since its eigenvalues become 1/λ and stay positive; and Q^T S Q for an orthogonal matrix Q is positive definite, shown either through similarity (same eigenvalues as S) or by rewriting its energy as the energy of S evaluated at Qx.
Positive semidefinite matrices (38:02)
Strang identifies the borderline case where a leading determinant reaches exactly zero, meaning one eigenvalue is zero while the trace confirms the other is positive: this is positive semidefinite. He illustrates with the all-ones matrix, a rank-one matrix whose only nonzero eigenvalue is 3, showing it decomposes as 3 times the outer product of the normalized all-ones eigenvector with itself, matching the general QΛQ^T pattern for symmetric matrices.
Before you watch
- Watch Lecture 4 on eigenvalues and symmetric matrices first, since this lecture builds directly on the spectral theorem
S = QΛQ^T. - Familiarity with computing a 2x2 determinant and doing one step of elimination helps follow the worked examples.
Check your understanding
- What are the five equivalent tests for a symmetric matrix to be positive definite?
- Why does the energy function
x^T S xproduce a bowl-shaped graph for a positive definite matrix? - Why does gradient descent converge slowly when a matrix's eigenvalues are very different in size?
- Why is
S + Tpositive definite wheneverSandTare, and why isS^-1positive definite? - What distinguishes a positive semidefinite matrix from a positive definite one, and how does the all-ones matrix illustrate this?
Chapters
- 0:00 <Untitled Chapter 1>
- 3:09 Positive Definite Matrices
- 5:32 Indefinite Matrix
- 6:23 Leading Determinants
- 9:55 Definition of a Positive Definite Matrix
- 13:53 Graph of a Positive Definite Matrix
- 21:38 First Derivatives
- 22:22 Gradient of F
From the YouTube description
MIT 18.065 Matrix Methods in Data Analysis, Signal Processing, and Machine Learning, Spring 2018
Instructor: Gilbert Strang
View the complete course: https://ocw.mit.edu/18-065S18
YouTube Playlist: https://www.youtube.com/playlist?list=PLUl4u3cNGP63oMNUHXqIUcrkS2PivhN3k
In this lecture, Professor Strang continues reviewing key matrices, such as positive definite and semidefinite matrices. This lecture concludes his review of the highlights of linear algebra.
License: Creative Commons BY-NC-SA
More information at https://ocw.mit.edu/terms
More courses at https://ocw.mit.edu
← Lecture 4: Eigenvalues and Eigenvectors · Lecture 6: Singular Value Decomposition (SVD) →